I’m back to Octopress for now!! Ghost was cool, but I never migrated my content. I will probably convert this to Astro at some point, but for now it’s Octopress. Thank God for Claude Code to make the mainteance easier.
Moving to a New Blogging Platform
Octopress has treated me well over the years, but with the advent of more modern blogging platforms like Ghost I decided it was time to switch. Check out my new ghost blog at blog.tleyden.net (sorry this apparently got domain hijacked after I let it expire).
Ghost advantages
- Open source for hackability.
- Hosted and self-hosted offerings, with easy migration either direction.
- Very clean interface like Medium.
- You own all your content, unlike Medium.
- Extensible with plugins and themes.
- Easy to inject markdown snippets or embed many types of content.
- WYSIWIG editing straight from the browser is really nice and feels like a faster workflow.
- There are options to create a paid newsletter (a la substack).
Ghost disadvantages
- Since it’s not a static blog, you can’t just push to github pages and be done with it.
- Self-hosting is a bit of a pain. My server ran out of memory and I ended up throwing in the towel and going with the Ghost Pro hosted version for now. (though I can always easily go back later, which is nice)
- Ghost Pro costs money.
Octopress advantages
- When published to github pages, you get an amazing lightning-fast hosting service completely free.
- Markdown-centric means the content is very portable to other places that natively support markdown.
Octopress disadvantages
- Maintaining the ruby tooling can be a bit of a pain. Upgrading is scary, so I got stuck at an old version.
- Extensibility seemed like a pain so I personally didn’t bother.
- Feels a bit archaic at this point.
Installing Autoware on Ubuntu 20.04
This is a log of my experience installing Autoware on my bare metal laptop running Ubuntu 20.04. I had a ton of stumbling blocks but stuck with it and eventually got it working. I documented it along the way, so if you hit any of those same issues this might be useful to you.
As a warning, this blog post is pretty messy because of all those stumbling blocks, so you’re probably better off just following the official autoware installation docs and referring to this in case you run into the same problems.
Good luck!!
- My system
- Pre-install steps
- Installation (docker-based)
- Run a planning simulation
- Install the gdown utility
- Download maps
- Launch autoware – take 1
- Upgrade to CUDA 11.6
- Upgrade to CUDA 11.6 – take 2
- Start autoware docker container take 2
- Install Nvidia container toolkit
- Install cuDNN
- Install TensorRT
- Start autoware docker container take 3
- Launch autoware take 2
- Start autoware docker container take 4
- Launch autoware take 3
- References
My system
- Ubuntu 20.04
- System76 Oryx Pro laptop, 2017
- Nvidia GeForce GTX 1070
- Nvidia Driver Version: 470.141.03 CUDA Version: 11.4 (upgraded during this blog post to Driver Version: 510.73.05 CUDA Version: 11.6)
Pre-install steps
Choose Ubuntu Linux version
Autoware currently supports both 20.04 and 22.04 (but not 18.04), and I decided to go with 20.04 since it was the next LTS version after the version I had installed (18.04).
I noticed that autoware recommended cuda version of 11.6, which only has official downloads for 20.04 and not 22.04, so that made me think that Ubuntu 20.04 was the better choice.
Here are the steps to upgrade to Ubuntu 20.04: official instructions.
Docker vs source install
I decided to go with the easier docker install until I had a need to use the source install.
Clean out old ros installs
1 2 3 | |
Installation (docker-based)
Install docker engine
Install docker engine based on these instructions. This links to the snapshot of the instructions that I used (as do below links). If you want to use the latest instructions, change the 0423b84ee8d763879bbbf910d249728410b16943 commit hash in the URL to main.
Nvidia container toolkit
Install the nvidia container toolkit based on these instructions.
After this step I was able to run nvidia-smi within the container:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 | |
Rocker
Rocker is an alternative to Docker compose used by Autoware.
Installed rocker based on these instructions.
After this step, running rocker shows the rocker help.
Start autoware docker container
I ran:
1
| |
but got this error:
1 2 3 4 | |
Error workaround
Using the approach suggested in this github post to add -e NVIDIA_DISABLE_REQUIRE=true, I ran the new command:
1
| |
which seemed to work, as it dropped me into a container:
1 2 | |
Based on the response from the super helpful folks at Autoware in this discussion I determined I needed to upgrade my Cuda version based on these instructions. (see later step below)
Install vcstool
In the source instructions, it mentions that autoware depends on vcstool, which is a tool that makes it easy to manage code from multiple repos.
Install with:
1 2 3 | |
Setup workspace (from within container)
In the container shell (started above):
1 2 3 4 5 6 7 | |
it took about 40 mins to build:
1 2 | |
Run a planning simulation
According to the docs: “Ad hoc simulation is a flexible method for running basic simulations on your local machine, and is the recommended method for anyone new to Autoware.”, but there are no docs on how to do run an ad hoc simulation, so I am going to try a planning simulation based on the planning simulation docs
Install the gdown utility
This tool is needed to download the map data.
1
| |
Download maps
In the container started above:
1 2 3 | |
Launch autoware – take 1
From inside the container:
1 2 | |
I’m seeing a ton of errors like:
1
| |
and red-herring error
1
| |
and possible red herring error
1
| |
These issues seem related:
- https://github.com/autowarefoundation/autoware.universe/issues/630
- https://github.com/autowarefoundation/autoware.universe/issues/641
- https://github.com/autowarefoundation/autoware.universe/issues/643
I think this error matters the most, since I get it if I try to launch rviz directly:
1
| |
The same error was reported in https://github.com/ros2/rviz/issues/753 and https://github.com/NVIDIA/nvidia-docker/issues/1438.
I will update my nvidia driver as alluded to above, remove the -e NVIDIA_DISABLE_REQUIRE=true workaround, and retry.
Upgrade to CUDA 11.6
I erroneously used the official nvidia instructions for installing cuda, so instead use the official autoware instructions to install cuda rather than the steps below.
1 2 3 4 5 6 7 | |
It failed on the last step:
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
Based on this advice, I’m going to re-install. First I am purging:
1
| |
Reboot.
I still had some libnvidia packages, so I purged them with:
1
| |
Since I’m running a system76 laptop, I went to them for support in order to upgrade the nvidia drivers.
1
| |
and now I’m running nvidia 515.65.01:
1 2 3 4 | |
Upgrade to CUDA 11.6 – take 2
Again for this step I erroneously used the official nvidia instructions for installing cuda, so instead use the official autoware instructions to install cuda rather than the steps below.
1 2 3 4 | |
This succeeded, but now nvidia-smi does not work:
1 2 | |
I later realized that I diverged from the autoware instructions in two ways:
- I should have run
cuda_version=11-4 apt install cuda-${cuda_version} --no-install-recommends - There are a few post-installation actions that need to be run
Post-installation actions:
1 2 3 | |
Fixing nvidia-smi error
I simply rebooted, and now nvidia-smi works. Note that the cuda version went from 11.7 to 11.6. The strange thing is that previously I idn’t have the cuda packages installed.
1 2 3 4 5 | |
Start autoware docker container take 2
1
| |
but got error:
1 2 | |
I realized I’m still missing several requirements:
- Nvidia container toolkit – I had this previously, but it was uninstalled.
- TensorRT and cuDNN – ditto
Install Nvidia container toolkit
I installed nvidia container toolkit based on these autoware instructions
And now it’s able to start a container and run nvidia-smi:
1 2 3 4 5 | |
Install cuDNN
1 2 3 4 5 6 | |
This error was caused by another divergence from the autoware instructions, where I didn’t run this step:
1
| |
I re-ran all of these steps from the autoware docs:
1 2 3 4 5 | |
and now this step worked:
1
| |
Pin the libraries at those versions with:
1
| |
Install TensorRT
Using these instructions:
1 2 3 | |
Start autoware docker container take 3
1 2 3 4 5 6 7 8 9 | |
This worked, but at first I was very confused that it actually worked.
It drops you back at the prompt with no meaningful output, but if you look closely, it’s a different prompt. The hostname changes from your actual hostname (apollo in my case), to this cryptic container name (0b1ce9ed54bd).
Note that if you run this in the container:
1 2 3 | |
you will see meaningful output, whereas if you run that on your host, you will most likely see ros2: command not found, unless you had installed ros2 on your host previously.
Launch autoware take 2
(also requires maps download, see above)
From inside the container:
1 2 | |
But the same errors are showing up:
1 2 3 4 | |
Note that these errors are also shown if I run rviz2 from within the container.
1 2 3 4 5 6 7 | |
Workaround rviz2 errors by passing in /dev/dri device
Relevant github issues:
The recommended fix is:
1
| |
I don’t currently have either of those libraries installed:
1 2 | |
I installed these packages on the host (outside the container), but that didn’t fix the issue.
I tried installing the packages in the container, but that didn’t work either.
There is a discrepancy between glxinfo on the host vs container.
In this container:
1
| |
It is returning an error:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
Whereas on the host:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 | |
This stack overflow post suggested a workaround, and according to the rocker docs
“For Intel integrated graphics support you will need to mount the /dev/dri directory as follows:”
1
| |
After restarting a container with that flag, it no longer shows the libGL error: MESA-LOADER: failed to retrieve device information error.
I posted a question on the autoware forum to find out why this workaround was needed. Apparently there is another way to solve this problem by forcing the use of the nvidia gpu rather than the intel graphics card:
1 2 3 4 | |
but I haven’t verified this yet.
Start autoware docker container take 4
Add the --devices /dev/dri flag:
1
| |
And now it finally works!! Running rviz2 from within the container shows the rviz window:

Launch autoware take 3
(also requires maps download, see above)
From inside the container:
1 2 | |
and rviz launched with autoware configured:

Phew! That was a lot harder than I thought it was going to be! It would have gone smoother if:
- My nvidia/cuda drivers were up-to-date with Cuda 11.6 and a suitable nvidia driver version.
- I’d followed the autoware docs rather than using the nvidia docs – the small divergences mattered a lot. (:facepalm)
- I had known about the
--devices /dev/drior nvidia “prime-select” workarounds.
Continued ..
Unfortunately after these steps, rviz2 is still using the integrated cpu driver rather than the GPU.
See this follow-up post on blog.tleyden.net (sorry this apparently got domain hijacked after I let it expire) to see how to get it running on the GPU.
References
Installing Ghost on AWS Lightsail With SQLite
Here are my requirements for a Ghost blogging platform backend:
- Cheap – ideally under $5 / month
- Ability to setup multiple blogs if I later want to add a new blog hosted on a different domain: so blog1.domainA.com + and blog2.domainB.com, without increasing cost.
- Easy to manage and backup
Non-requirements:
- High traffic
- Avoiding CLI or some server management (would be nice, but does that exist for < $5 month?)
And here is the tech stack:
- AWS Lightsail instance running Ubuntu 18
- SQLite
- Nginx
- Node.js
- Ghost Node.js module(s)
SQLite was chosen over MySQL since this is one less “moving part” and slightly easier to manage. See this blog post for the rationale.
Launch a Lightsail instance
Lightsail seems like a good value since you can get a decent sized instance and a static IP for $5.
Login to the AWS console and create a Lightsail instance with the following specs:
- Blueprint: OS Only Ubuntu 18.04 LTS
- SSH key: upload your
~/.ssh/id_rsa.pub(maybe make a copy and rename it with a better name to easily find it in the AWS console later) - Instance Plan: $5/mo with 1GB or RAM, 1 vCPU, 40 GB SSD and 2 TB of transfer. Ghost recommends at least 1 GB of RAM, so it’s probably better to use this instance size or greater.
- Identify your instance: rabbit (or whatever you wanna call it!)
You should see the following:

Create a static ip
Go to the Lightsail Networking section, and choose “Attach static ip”. Associate the static ip with the lightsail instance, and make a note of it as you will need in the next step.
Add DNS A record
Go to your DNS register where you registered your blog domain name (eg, Namecheap), and add a new A record as follows:

- Use “blog” for the host if you want the blog named “blog.yourdomain.com”, but you could also name it something else.
- Use the public static ip address created in the previous step.
Install Ghost dependencies
ssh in via ssh ubuntu@<your ligthsail instance ip>
Update the apt package list:
1
| |
Install nginx:
1 2 | |
Install nodejs:
Add the NodeSource APT repository for Node 12, then install nodejs
1 2 | |
Install Ghost-CLI
1
| |
Create ghost blog
Create a directory to hold the blog:
1 2 3 4 | |
Install Ghost:
1
| |
If you get an error about the node.js version being out of date, see the “Error installing ghost due to node.js being out of date” section below.
Here is how I answered the setup questions, but you can customize to your needs:
- Enter your blog URL: http://blog1.domainA.com
- Do you wish to setup Nginx?: Yes
- Do you wish to setup SSL?: No
- Do you wish to setup Systemd?: Yes
- Do you want to start Ghost?: Yes
I decided to setup SSL in a separate step rather than initially, but the more secure approach would be to use https instead, eg https://blog1.domainA.com for the blog URL and answer Yes to the setup SSL question, which will trigger SSL setup initially.
If you do setup SSL, you will need to open port 443 in the Lightsail console, otherwise it won’t work. See the “Setup SSL” section below for instructions.
Create Ghost admin user
This part is a little scary, (and ghosts are scary), but Ghost basically puts your blog unprotected to the world without an admin user. The first person that stumbles across it gets to become the admin user. You want that to be you!
Quickly go to http://blog1.domainA.com and create the Ghost admin user.
Configure blog2 and map it’s DNS
Go to your DNS register where you registered your blog domain name (eg, Namecheap), and add a new A record as follows:
- Use “blog” for the host if you want the blog named “blog.domainB.com”, but you could also name it something else.
- Use the public static ip address from the Lightsail AWS console.
1 2 3 4 | |
Install Ghost:
1
| |
Use the same steps above, except for the blog URL use: http://blog.domainB.com
Congrats!
You now have two separate Ghost blogging sites setup on a single $5 / mo AWS Lightsail instance.
Appendix
Error installing ghost due to node.js being out of date
If you see this error:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 | |
Fix option #1 – specify an older version of ghost
Find an older version of ghost that is compatible with the node.js you have installed, then specify that version of ghost when installing it:
1
| |
How do you find that version? I happened to have another blog folder that I had previously installed, so I just used that. Maybe on the ghost website they have a compatibility chart.
The downside of this approach is that you won’t have the latest and greatest version of ghost, including security updates. The upside though is that you won’t break any existing ghost blogs on the same machine by upgrading node.js.
Fix option #2 – upgrade to a later node.js and retry
In the error above, it mentions that ghost requires node.js 14.17.0 or above.
The downside is that this could potentially break other existing ghost blogs on the same machine that are not compatible with the later version of node.js. Using containers to isolate dependencies would be beneficial here.
Upgrade to that version of node.js based on these instructions:
1 2 | |
Run node -v to verify that you’re running a recent enough version:
1 2 | |
Update the ghost cli version:
1
| |
Retry the ghost install command:
1
| |
and this time it should not complain about the node.js version.
Setup SSL
During installation, you can answer “Yes” to setup SSL, and it will ask you for your email and use letsencrypt to generate a certificate for you. See this page for more details.
But you must also open port 443 in your Lightsail firewall, otherwise it won’t work.

Auto-renew SSL cert every 90 days
Lets Encrypt certificates expire after 90 days. To avoid downtime on your site, you should auto-renew the certificates. See this blog post for details.
I tried to follow the blog post, and ran ghost setup ssl-renew in my blog folder, but after switching to root with sudo su, I noticed this existing cron entry:
1 2 | |
So it looks like it is already setup to renew the certs every day.
References
OpenWhisk Action Sequences
This will walk you through getting up and running from scratch with Apache OpenWhisk on OSX, and setting up an Action Sequence where the output of one OpenWhisk Action is fed into the input of the next Action.
Install OpenWhisk via Vagrant
1 2 3 4 5 6 7 8 | |
You should see reams of output, followed by:
1 2 3 4 | |
SSH into Vagrant machine and run OpenWhisk CLI
1
| |
Now you can access the OpenWhisk CLI:
1 2 3 4 5 6 7 8 9 10 11 | |
Re-run the “Hello world” via:
1 2 3 4 | |
Hello Go/Docker
I tried following the instructions on James Thomas’ blog for running Go within Docker, but ran into an error (see Disqus comment), and so here’s how I worked around it.
First create a simple Go program and cross compile it. Save the following to exec.go:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
Cross compile it for Linux:
1
| |
Pull the upstream Docker image:
1
| |
Create a custom docker image based on openwhisk/dockerskeleton:
1 2 3 | |
Build and test:
1 2 3 | |
OpenWhisk Hello Go/Docker
Push up the docker image to dockerhub:
1
| |
Create the OpenWhisk action:
1
| |
Invoke the action to verify it works:
1 2 3 4 5 6 7 8 | |
Define custom actions
Get a list of AWS users using aws-go-sdk
Save this to main.go
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 | |
Build and package into docker image, and push up to docker hub
1 2 3 | |
Create an OpenWhisk action:
1
| |
Invoke it:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 | |
Write to a CloudantDB
Cloudant Setup
Create a Cloudant database via the Bluemix web admin.
Under the Permissions control panel section for the database, choose Generate a new API key.
Check the _writer permission and make a note of the Key and Password
Verify connectivity by making a curl request:
1 2 3 4 | |
OpenWhisk + Cloudant
1
| |
I’m currently getting this error:
1
| |
Switch to BlueMix
At this point I swiched to the OpenWhisk on Bluemix, and downloaded the wsk cli from the Bluemix website, and configure it with my api key per the instructions. Then I re-installed the action via:
1
| |
and made sure it worked by running:
1
| |
Cloudant Setup
Following these instructions:
You can get your Bluemix Org name (maybe the first part of your email address by default) and BlueMix space (dev by default) from the Bluemix web admin.
1 2 | |
Refresh packages:
1 2 3 4 5 | |
It didn’t work according to the docs, and no bindings were created even though I had created a Cloudant database in the Bluemix admin earlier.
I retried the package bind command that had failed earlier:
1
| |
and this time success!!
1
| |
Try writing to the db with:
1
| |
and you should get a response like:
1 2 3 4 5 | |
Connect them in a sequence
Create a new package binding pinned to a particular db
The /yournamespace/myCloudant/write action expects a dbname parameter, but the upstream fetch_aws_keys doesn’t contain that parameter. (and it’s better that it doesn’t, to reduce decoupling). So if you try to connect the two actions in a sequence at this point, it will fail.
1
| |
Create sequence action
Create a sequence that will invoke these actions in sequence:
1
| |
- Fetch the AWS keys
- Write the doc containing the AWS keys to the
testdbdatabase bound to the myCloudantTestDb package
Try it out:
1 2 3 4 5 6 | |
To view the resulting document:
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
Drive with a scheduler
Let’s say we wanted this to run every minute.
First create an alarm trigger that will fire every minute:
1
| |
Now create a rule that will invoke the fetch_and_write_aws_keys action (which is a sequence action) whenever the everyMinute feed is triggered:
1
| |
To verify that it is working, check your cloudant database to look for new docs:
1
| |
Or you can also monitor the activations:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 | |
Running PostgreSQL in Docker
This walks you through:
- Running Postgres locally in a docker container using docker networking (rather than the deprecated container links functionality that is mentioned in the Postgres Docker instructions.
- Deploying to Docker Cloud
Basic Postgres container with docker networking
Create a user defined network
1
| |
Launch Postgres in that network
The main parameter you will need to provide to postgres is a root db password. Replace ********* with a good password and run this command:
1
| |
Launch psql and connect to Postgres
1 2 3 4 5 6 | |
You now have a working postgres database server.
Using a mounted volume for persistence
When running postgres under docker, most likely want to persist the database files on the host, rather than having them in the container.
First, remove the previous container with:
1
| |
Go into the /tmp directory:
1
| |
Launch a container and use /tmp/pgdata as the host directory to mount as a volume mount, which will be mounted in the container in /var/lib/postgresql/data, which is the default location where Postgres stores it’s data. The /tmp/pgdata directory will be created on the host if it doesn’t already exist.
1
| |
List the contents of /tmp/pgdata and you should see several Postgres files:
1 2 | |
Launch phppgadmin Container
First create a user
1
| |
Now you will be in a shell inside the docker container
1 2 3 4 | |
Launch pgpadmin
1
| |
Login
In your browser, open http://localhost:8080/ and you should see the phpadmin login screen:

Login with user/pass credentials created earlier:
- username:
testuser - password:
**********

Deploying to Docker Cloud
Security warning! This is not a secure deployment and it’s not recommended to run this in production without a thorough audit by a security specialist.
Deploy Stack
Create a new stack and paste it into the box
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
For example:

Create user
Find the postgres-server container and hit the Terminal menu to get a shell on that container.
Enter:
1 2 3 | |
Login to Web UI
Find the phppgadmin service in the Docker Cloud Web UI, and look for the service endpoint, which should look something like this:
http://phppgadmin.postgres.071a32d40.svc.dockerapp.io:8085/
Login with user/pass credentials created earlier:
- username:
testuser - password:
**********
Understanding Function Closures in Go
Function closures are really powerful.
Essentially you can think of them like stateful functions, in the sense that they encapsulate state. The state that they happen to capture (or “close over” — hence the name “closure”) is everything that’s in scope when they are defined.
First some very basic higher order functions.
Higher order functions
Functions that take other functions and call them are called higher order functions. Here’s a trivial example:
1 2 3 4 5 6 7 8 9 10 11 12 | |
In the main() function, we define a function called mySender and pass it to the sendLoop() function. sendLoop() takes a confusing looking argument called sender func() — the parameter name is sender, and the parameter type is func(), which is a function that takes no arguments and returns no values.
To make this slightly less confusing, we can define a named SenderFunc function type and use that:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 | |
sendLoop() has been updated to take SenderFunc as an argument, which is easier to read than taking a func() as an argument (which looks a bit like a function call!) If the SenderFunc type took more parameters and/or returned more values, having this in a defined type would be crucial for readability.
Adding a return value
Let’s make it slightly more realistic — let’s say that the sendLoop() might need to retry calling the SenderFunc passed to it a few times until it actually works. So the SenderFunc definition will need to be updated so that it returns a boolean that indicates whether a retry is necessary.
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 | |
One thing to note here is the clean separation of concerns — all sendLoop() knows is that it gets a SenderFunc which it should call and it will return a boolean indicator of whether or not it worked or not. It knows absolutely nothing about the inner workings of the SenderFunc, nor does it care.
A stateful sender — the wrong way
You have a new requirement that you need to only retry the SenderFunc 10 times, and then you should give up.
Your first inclination might be to take this approach:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 | |
This will work, but it makes the sendLoop() less generally useful. What happens when your co-worker hears about this nifty sendLoop() you wrote, and wants to use it with their own SenderFunc but wants it to retry 100 times? (side note: your SenderFunc implementation simply prints to the console, whereas theirs might write to a Slack channel, yet the sendLoop() will still work!)
To make it more generic, you could take this approach:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 | |
Which will work — but there’s a catch. Now that you’ve changed the method function signature of sendLoop() to take a second argument, all of the code that consumes sendLoop() will now be broken. If this were an exported function, it would be an even worse problem.
Luckily there is a much better way.
A stateful sender — the right way using function closures
Rather than making sendLoop() do the retry-related accounting and passing it parameters for that accounting, you can make the SenderFunc handle this and encapsulate the state via a function closure. In this case, the state is the number of retries that have been attempted, which will start at 0 and then increase on every call to the SenderFunc
How can SenderFunc keep internal state? It can “close over” any values that are in scope, which become associated with the function instance (I’m calling it an “instance” because it has state, as we shall see) and will be bound to the function instance as long as the function instance is around.
Here’s what the final code looks like:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 | |
The counter state variable is bound to the mySender function instance, which is able to update counter on every failed send attempt since the function “closes over” the counter variable that is in scope when the function instance is created. This is the heart of the idea of a function closure.
The sendLoop() doesn’t know anything about the internals of the SenderFunc in terms of how it tracks whether or not it should retry or not, it just treats it as a black box. Different SenderFunc implementations could use vastly different rules and/or states for deciding whether the sendLoop() should retry a failed send.
If you wanted to make it even more flexible, you could update the SenderFunc to return a time.Duration in addition to a bool to indicate retry, which would allow you to implement “backoff retry” strategies and so forth.
What about thread/goroutine safety?
If you’re passing the same function instances that have internal state (aka function closures) to multiple goroutines that are calling it, you’re going to end up causing data races. There’s nothing special about function closures that protect you from this.
The simplest way to deal with is to make a new function instance for each goroutine you are sending the function instance to, which is probably what you want. In theory though, you could also wrap the state update in a mutex, which is probably not what you want since that will cause goroutines to block eachother trying to grab the mutex.
Tuning the Go HTTP Client Settings for Load Testing
While working on a load testing tool in Go, I ran into a situation where I was seeing tens of thousands of sockets in the TIME_WAIT state.
Here are a few ways to get into this situation and how to fix each one.
Repro #1: Create excessive TIME_WAIT connections by forgetting to read the response body
Run the following code on a linux machine:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 | |
and in a separate terminal while the program is running, run:
1
| |
and you will see this number constantly growing:
1 2 3 4 5 6 7 8 9 | |
Fix: Read Response Body
Update the startLoadTest() method to add the following line of code (and related imports):
1 2 3 4 5 6 7 8 9 10 11 12 | |
Now when you re-run it, calling netstat -n | grep -i 8080 | grep -i time_wait | wc -l while it’s running will return 0.
Repro #2: Create excessive TIME_WAIT connections by exceeding connection pool
Another way to end up with excessive connections in the TIME_WAIT state is to consistently exceed the connnection pool and cause many short-lived connections to be opened.
Here’s some code which starts up 100 goroutines which are all trying to make requests concurrently, and each request has a 50 ms delay:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 | |
In another shell run netstat, note that the number of connections in the TIME_WAIT state is growing again, even though the response is being read
1 2 3 4 5 6 7 8 9 | |
To understand what’s going on, we’ll need to dig in a little deeper into the TIME_WAIT state.
What is the socket TIME_WAIT state anyway?
So what’s going on here?
What’s happening is that we are creating lots of short lived TCP connections, and the Linux kernel networking stack is keeping tabs on the closed connections to prevent certain problems.
From The TIME-WAIT state in TCP and Its Effect on Busy Servers:
The purpose of TIME-WAIT is to prevent delayed packets from one connection being accepted by a later connection. Concurrent connections are isolated by other mechanisms, primarily by addresses, ports, and sequence numbers[1].
Why so many TIME_WAIT sockets? What about connection re-use?
By default, the Golang HTTP client will do connection pooling. Rather than closing a socket connection after an HTTP request, it will add it to an idle connection pool, and if you try to make another HTTP request before the idle connection timeout (90 seconds by default), then it will re-use that existing connection rather than creating a new one.
This will keep the number of total socket connections low, as long as the pool doesn’t fill up. If the pool is full of established socket connections, then it will just create a new socket connection for the HTTP request and use that.
So how big is the connection pool? A quick look into transport.go tells us:
1 2 3 4 5 6 7 8 9 10 11 | |
- The
MaxIdleConns: 100setting sets the size of the connection pool to 100 connections, but with one major caveat: this is on a per-host basis. See the comments on theDefaultMaxIdleConnsPerHostbelow for more details on the implications of this. - The
IdleConnTimeoutis set to 90 seconds, meaning that after a connection stays in the pool and is unused for 90 seconds, it will be removed from the pool and closed. - The
DefaultMaxIdleConnsPerHost = 2setting below it. What this means is that even though the entire connection pool is set to 100, there is a per-host cap of only 2 connections!
In the above example, there are 100 goroutines trying to concurrently make requests to the same host, but the connection pool can only hold 2 sockets. So in the first “round” of the goroutines finishing their http request, 2 of the sockets will remain open in the pool, while the remaining 98 connections will be closed and end up in the TIME_WAIT state.
Since this is happening in a loop, you will quickly accumulate thousands or tens of thousands of connections in the TIME_WAIT state. Eventually, for that particular host at least, you will run out of ephemeral ports and not be able to open new client connections. For a load testing tool, this is bad news.
Fix: Tuning the http client to increase connection pool size
Here’s how to fix this issue.
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 | |
This bumps the total maximum idle connections (connection pool size) and the per-host connection pool size to 100.
Now when you run this and check the netstat output, the number of TIME_WAIT connections stays at 0
1 2 3 4 5 6 7 8 | |
The problem is now fixed!
If you have higher concurrency requirements, you may want to bump this number to something higher than 100.
Install Couchbase Server + Mobile on Docker Cloud
Deploy Couchbase Server and Sync Gateway on Docker Cloud behind a load balancer.
Also available as a screencast
Launch node cluster
Launch a node cluster with the following settings:
- Provider: AWS
- Region: us-east-1 (or whatever region makes sense for you)
- VPC: Auto (if you don’t choose auto, you will need to customize your security group)
- Type/Size: m3.medium or greater
- IAM Roles: None

Create Couchbase Server service
Go to Services and hit the Create button:

Click the globe icon and Search Docker Hub for couchbase/server. You should select the couchbase/server image:

Hit the Select button and fill out the following values on the Services Wizard:
- Service Name: couchbaseserver
- Containers: 2
- Deployment strategy: High Availability
- Autorestart: On failure
- Network: bridge

In the Ports section: Enable published on each port and set the Node Port to match the Container Port

Hit the Create and Deploy button. After a few minutes, you should see the Couchbase Server vervice running:

Configure Couchbase Server Container 1 + Create Buckets
Go to the Container section and choose couchbaseserver-1.
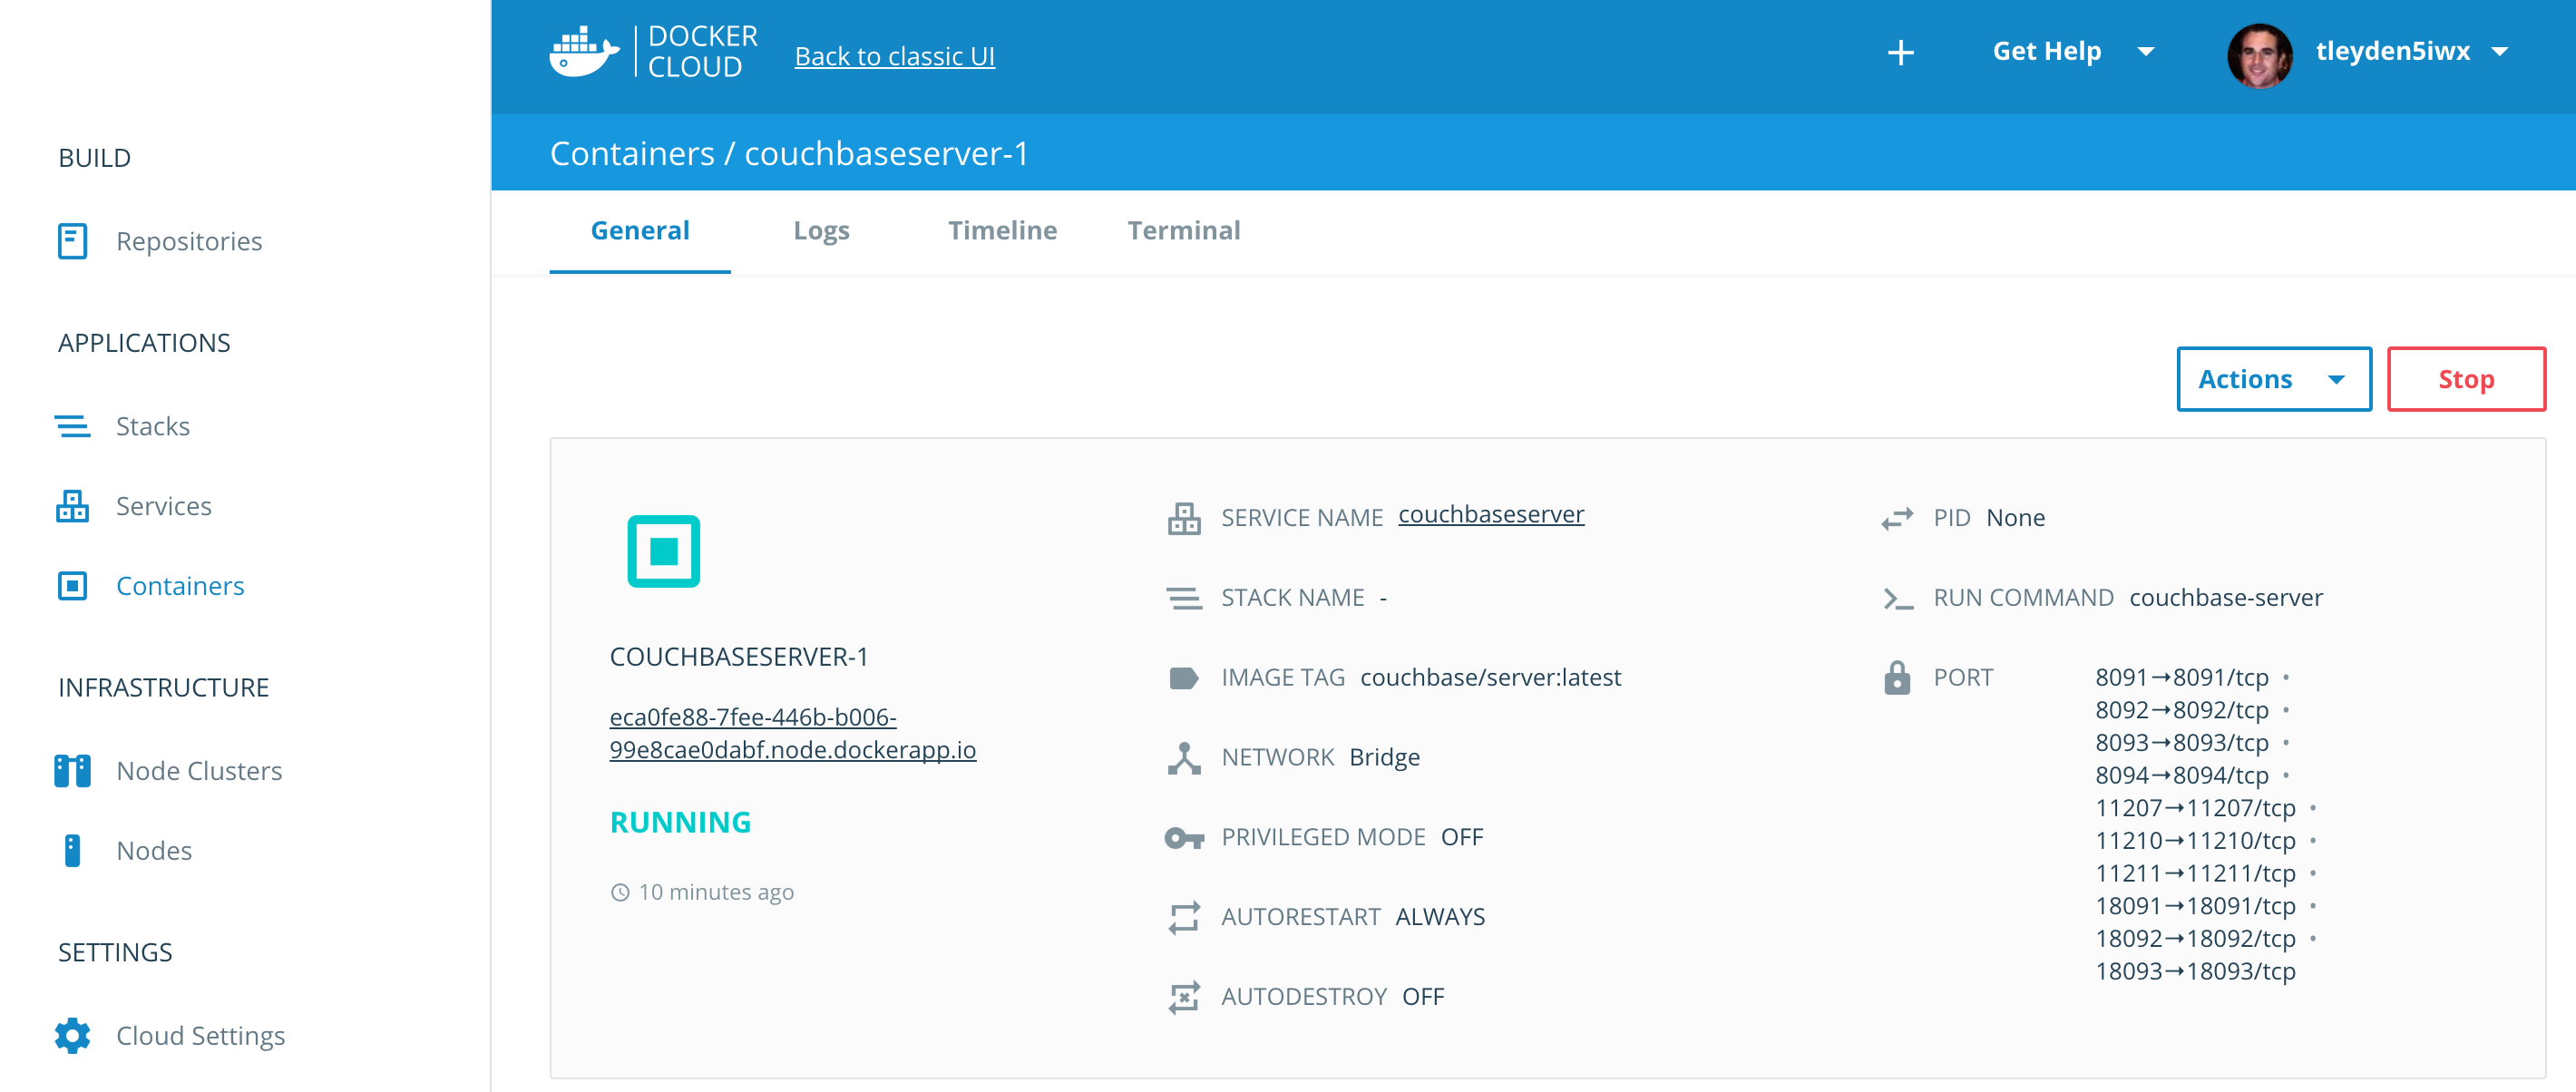
Copy and paste the domain name (eca0fe88-7fee-446b-b006-99e8cae0dabf.node.dockerapp.io) into your browser, adding 8091 at the end (eca0fe88-7fee-446b-b006-99e8cae0dabf.node.dockerapp.io:8091)
You should now see the Couchbase Server setup screen:

You will need to find the container IP of Couchbase Server in order to configure it. To do that, go to the Terminal section of Containers/couchbaseserver-1, and enter ifconfig.

Look for the ethwe1 interface and make a note of the ip: 10.7.0.2 — you will need it in the next step.
Switch back to the browser on the Couchbase Server setup screen. Leave the Start a new cluster button checked. Enter the 10.7.0.2 ip address (or whatever was returned for your ethwe1 interface) under the Hostname field.

and hit the Next button.
For the rest of the wizard, you can:
- skip adding the samples
- skip adding the default bucket
- uncheck Update Notifications
- leave Product Registration fields blank
- check “I agree ..”
- make sure to write down your password somewhere, otherwise you will be locked out of the web interface
Create a new bucket for your application:

Configure Couchbase Server Container 2
Go to the Container section and choose couchbaseserver-2.
As in the previous step, copy and paste the domain name (4d8c7be0-3f47-471b-85df-d2471336af75.node.dockerapp.io) into your browser, adding 8091 at the end (4d8c7be0-3f47-471b-85df-d2471336af75.node.dockerapp.io:8091)
Hit Setup and choose Join a cluster now with settings:
- IP Address: 10.7.0.2 (the IP address you setup the first Couchbase Server node with)
- Username: Administrator (unless you used a different username in the previous step)
- Password: enter the password you used in the previous step
- Configure Server Hostname: 10.7.0.3 (you can double check this by going to the Terminal for Containers/couchbaseserver-2 and running
ifconfigand looking for the ip of theethwe1interface)

Trigger a rebalance by hitting the Rebalance button:

Sync Gateway Service
Now create a Sync Gateway service.
Before going through the steps in the Docker Cloud web UI, you will need to have a Sync Gateway configuration somewhere on the publicly accessible internet.
Warning: This is not a secure solution! Do not use any sensitive passwords if you follow these steps
To make it more secure, you could:
- Use a Volume mount and have Sync Gateway read the configuration from the container filesystem
- Use a HTTPS + Basic Auth for the URL that hosts the Sync Gateway configuration
Create a Sync Gateway configuration on a github gist and get the raw url for the gist.
- Make sure to set the
servervalue tohttp://couchbaseserver:8091so that it can connect to the Couchbase Service setup in a previous step. - Use the bucket created in the Couchbase Server setup step above
In the Docker Cloud web UI, go to Services and hit the Create button again.
Click the globe icon and Search Docker Hub for couchbase/sync-gateway. You should select the couchbase/sync-gateway image.
Hit the Select button and fill out the following values on the Services Wizard:
- Service Name: sync-gateway
- Containers: 2
- Deployment strategy: High Availability
- Autorestart: On failure
- Network: bridge

In the Container Configuration section, customize the Run Command to use the raw URL of your gist, eg: https://gist.githubusercontent.com/tleyden/f260b2d9b2ef828fadfad462f0014aed/raw/8f544be6b265c0b57848

In the Ports section, use the following values:

In the Links section, choose couchbaseserver and hit the Plus button

Click the Create and Deploy button.
Verify Sync Gateway
Click the Containers section and you should have two Couchbase Server and two Sync Gateway containers running.

Click the sync-gateway-1 container and get the domain name (eca0fe88-7fee-446b-b006-99e8cae0dabf.node.dockerapp.io) and paste it in your browser with a trailing :4984, eg eca0fe88-7fee-446b-b006-99e8cae0dabf.node.dockerapp.io:4984
You should see the following JSON response:
1 2 3 4 5 6 7 8 | |
Setup Load Balancer
Click the Services section and hit the Create button. In the bottom right hand corner look for Proxies and choose dockercloud/haproxy

General Settings:
- Service Name: sgloadbalancer
- Containers: 1
- Deployment Strategy: High Availability
- Autorestart: Always
- Network: Bridge
Ports:
- Port 80 should be Published and the Node Port should be set to
80
Links:
- Choose sync-gateway and hit the Plus button
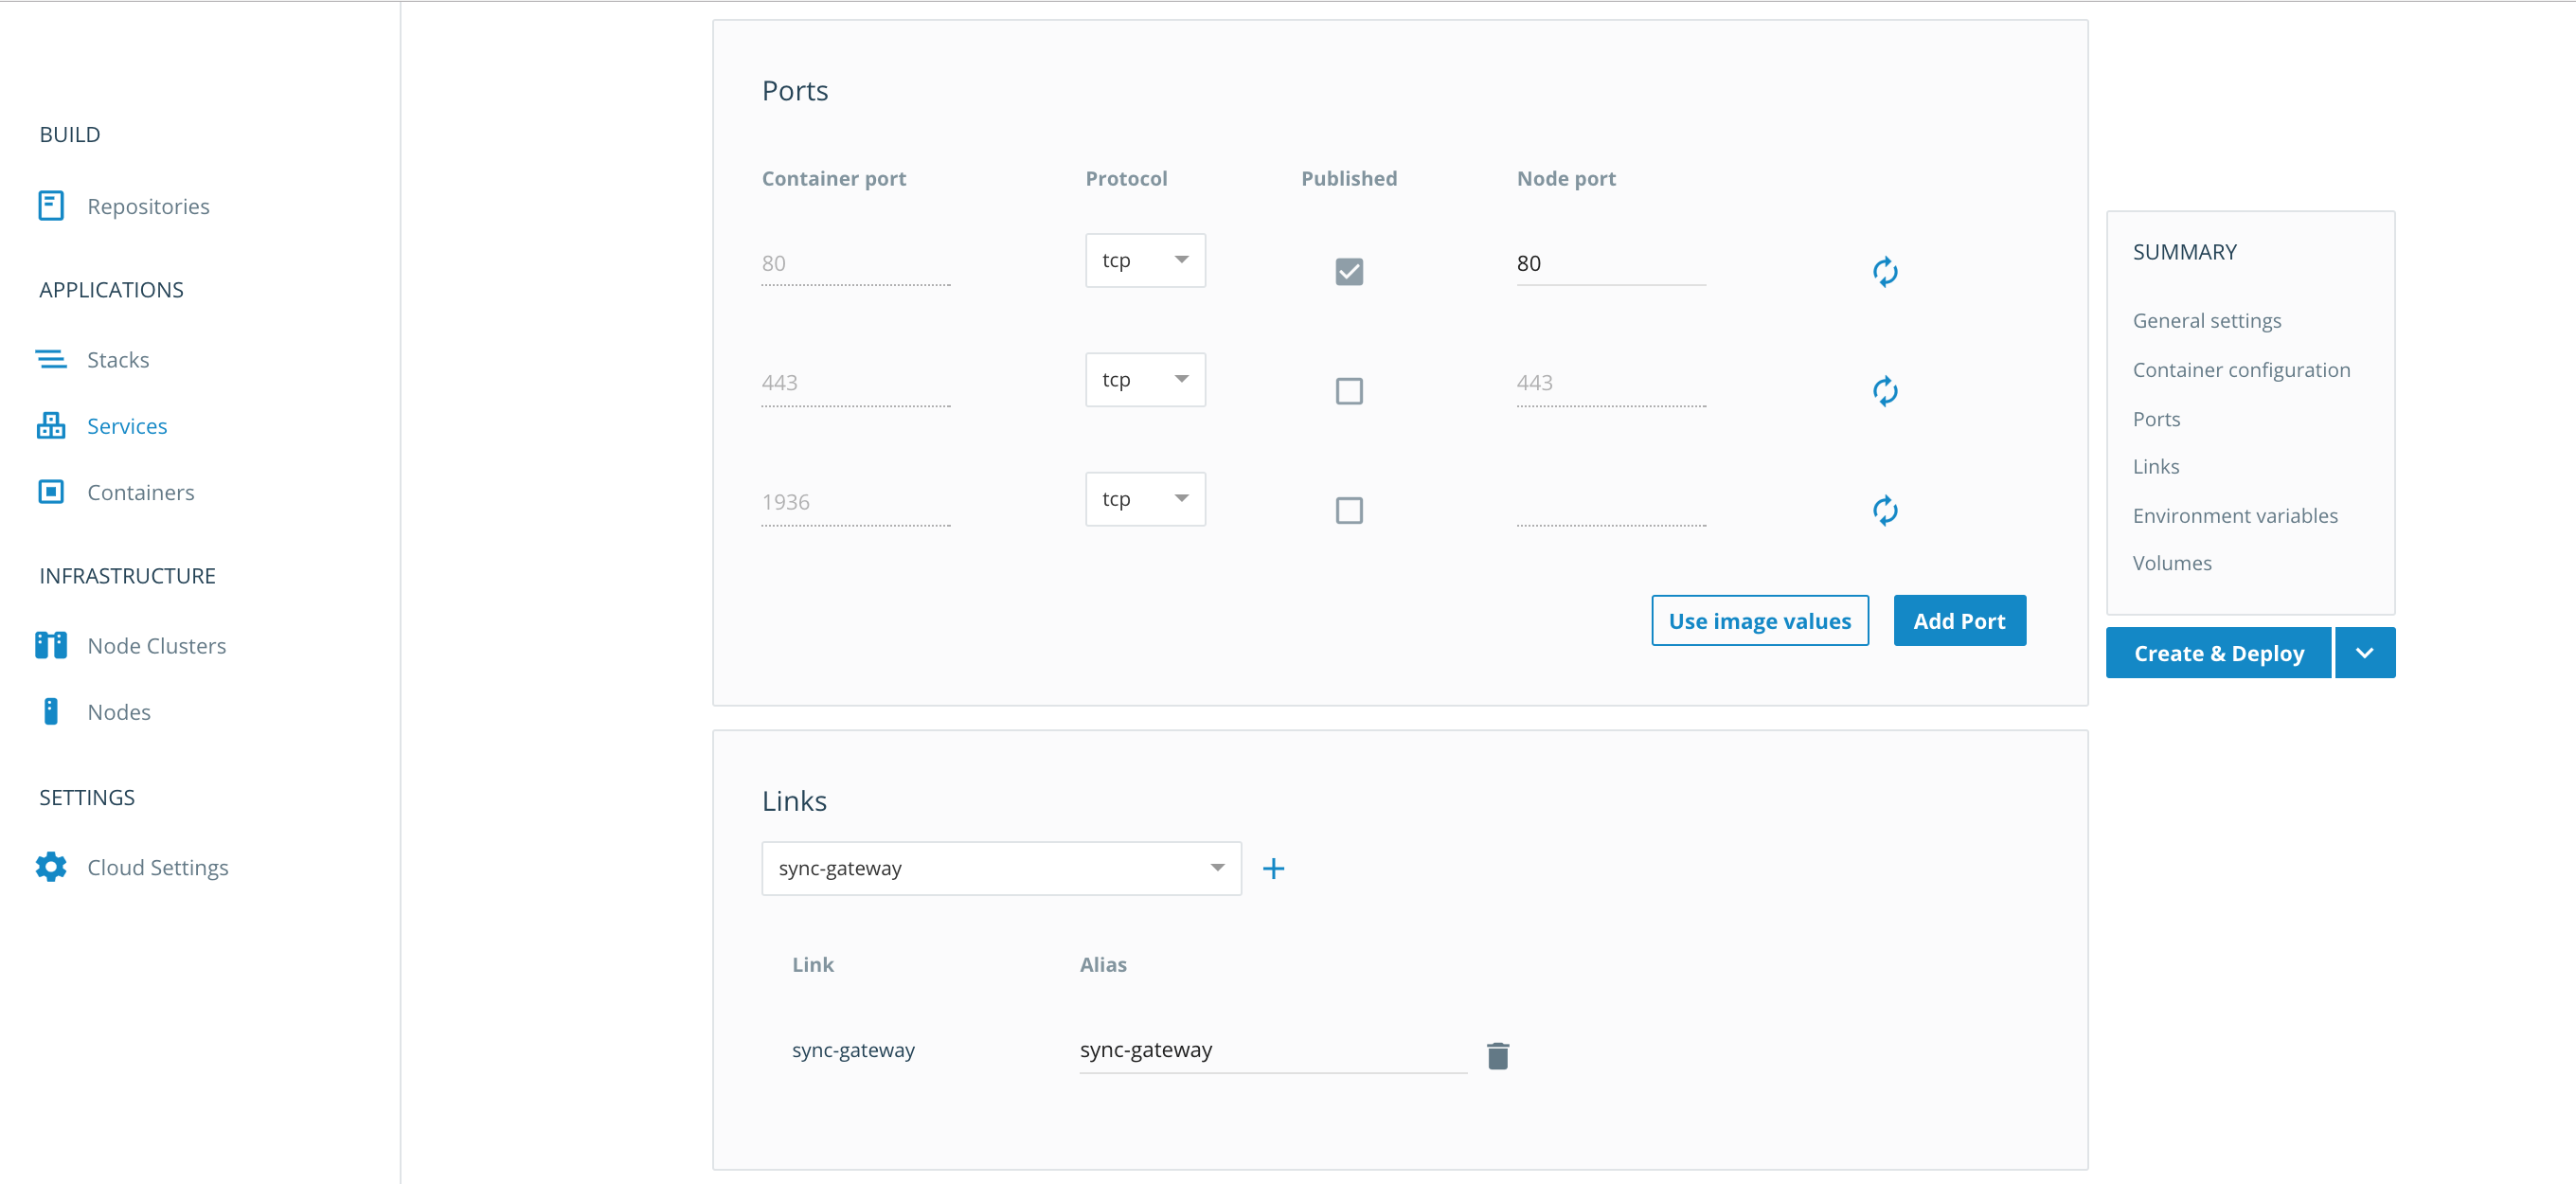
Hit the Create and Deploy button
Verify Load Balancer
Click the Containers section and choose sgloadbalancer-1.

Copy and paste the domain name (eg, eca0fe88-7fee-446b-b006-99e8cae0dabf.node.dockerapp.io) into your browser.
You should see the following JSON response:
1 2 3 4 5 6 7 8 | |
Congratulations! You have just setup a Couchbase Server + Sync Gateway cluster on Docker Cloud.
Deep Dive of What Happens Under the Hood When You Open a Web Page
This is a continuation of What Happens Under The Hood When You Open A Web Page, and it’s meant to be a deeper dive.
Clients and Servers
Remember back in the day when you wanted to know what time it was, and you picked up your phone and dialed 853-1212 and it said “At the tone, the time will be 8:53 AM?”.
Those days are over, but the idea lives on. The time service is identical in principal to an internet server. You ask it something, and it gives you an answer.
A well designed service does one thing, and one thing well.
With the time service, you can only ask one kind of question: “What time is it?”
With a DNS server, you can only ask one kind of question: “What is the IP address of organic-juice-for-dogs.io”
Clients vs Servers:
A “Client” can essentially be thought of as being a “Customer”. In the case of calling the time, it’s the person dialing the phone number. In the case of DNS, it’s the Google Chrome browser asking for the IP address.
A “Server” can be thought of as being a “Service”. In the case of calling the time, it’s something running at the phone company. In the case of DNS, it’s a service run by a combination of universities, business, and governments.
Web Browsers
The following programs are all web browsers, which are all technically HTTP Clients, meaning they are on the client end of the HTTP tube.
- Google Chrome
- Safari
- Firefox
- Internet Explorer
- Etc..
What web browsers do:
- Lookup IP addresses from DNS servers over the DNS protocol (which in turn sits on top of the UDP protocol)
- Retrieve web pages, images, and more from web servers over the HTTP protocol (which in turn sits on top of the TCP protocol)
- Render HTML into formatted “pages”
- Executes JavaScript code to add a level of dynamic behavior to web pages
Protocols
In the previous post, there were a few “protocols” mentioned, like HTTP.
What are protocols really?
Any protocol is something to make it possible for things that speak the same protocol to speak to each other over that protocol.
A protocol is just a language, and just like everyone in English-speaking countries agree to speak English and can therefore intercommunicate without issues, many things on the internet agree to speak HTTP to each other.
Here’s what a conversation looks like in the HTTP protocol:
1 2 | |
Almost everything that happens on the Internet looks something like this:
1 2 3 4 5 6 7 8 9 10 11 | |
Let’s look at a few protocols.
TCP and UDP
You can think of the internet as being made up of tubes. Two very common types of tubes are:
- TCP (Transmission Control Protocol)
- UDP (User Datagram Protocol)
Here’s what you might imagine an internet tube looking like:

IP
Really, you can think of TCP and UDP as internet tubes that are built from the same kind of concrete — and that concrete is called IP (Internet Protocol)
TCP wraps IP, in the sense that it is built on top of IP. If you took a slice of a TCP internet tube, it would look like this:
1 2 3 4 5 6 7 8 9 10 11 12 | |
Ditto for UDP — it’s also built on top of IP. The slice of a UDP internet tube would look like this:
1 2 3 4 5 6 7 8 9 10 11 12 | |
IP, or “Internet Protocol”, is fancy way of saying “How machines on the Internet talk to each other”, and IP addresses are their equivalent of phone numbers.
Why do we need two types of tubes built on top of IP? They have different properties:
- TCP tubes are heavy weight, they take a long time to build, and a long time to tear down, but they are super reliable.
- UDP tubes are light weight, and have no guarantees. They’re like the
¯\_(ツ)_/¯of internet tubes. If you send something down a UDP internet tube, you actually have no idea whether it will make it down the tube or not. It might seem useless, but it’s not. Pretty much all real time gaming, voice, and video transmissions go through UDP tubes.
HTTP tubes
If you take a slice of an HTTP tube, it looks like this:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
Because HTTP sits on top of TCP, which in turn sits on top of IP.
DNS tubes
DNS tubes are very similar to HTTP tubes, except they sit on top of UDP tubes. Here’s what a slice might look like:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
Actually, internet tubes are more complicated
So when your Google Chrome web browser gets a web page over an HTTP tube, it actually looks more like this:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 | |
Each of these random computers in between are called routers, and they basically shuttle traffic across the internet. They make it possible that any two computers on the internet can communicate with each other, without having a direct connection.
If you’re curious to know which computers are in the middle of your connection between you and another computer on the internet, you can run a nifty little utility called traceroute:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
So from my computer to the computer at google.com, it goes through all of those intermediate computers. Some have DNS names, like be-33651-cr01.sunnyvale.ca.ibone.comcast.net, but some only have IP addresses, like 162.151.78.93
Any one of those computers could sniff the traffic going through the tubes (even the IP tubes that all the other ones sit on top of!). That’s one of the reasons you don’t want to send your credit cards over the internet without using encryption.